Plausible
isn't proof.
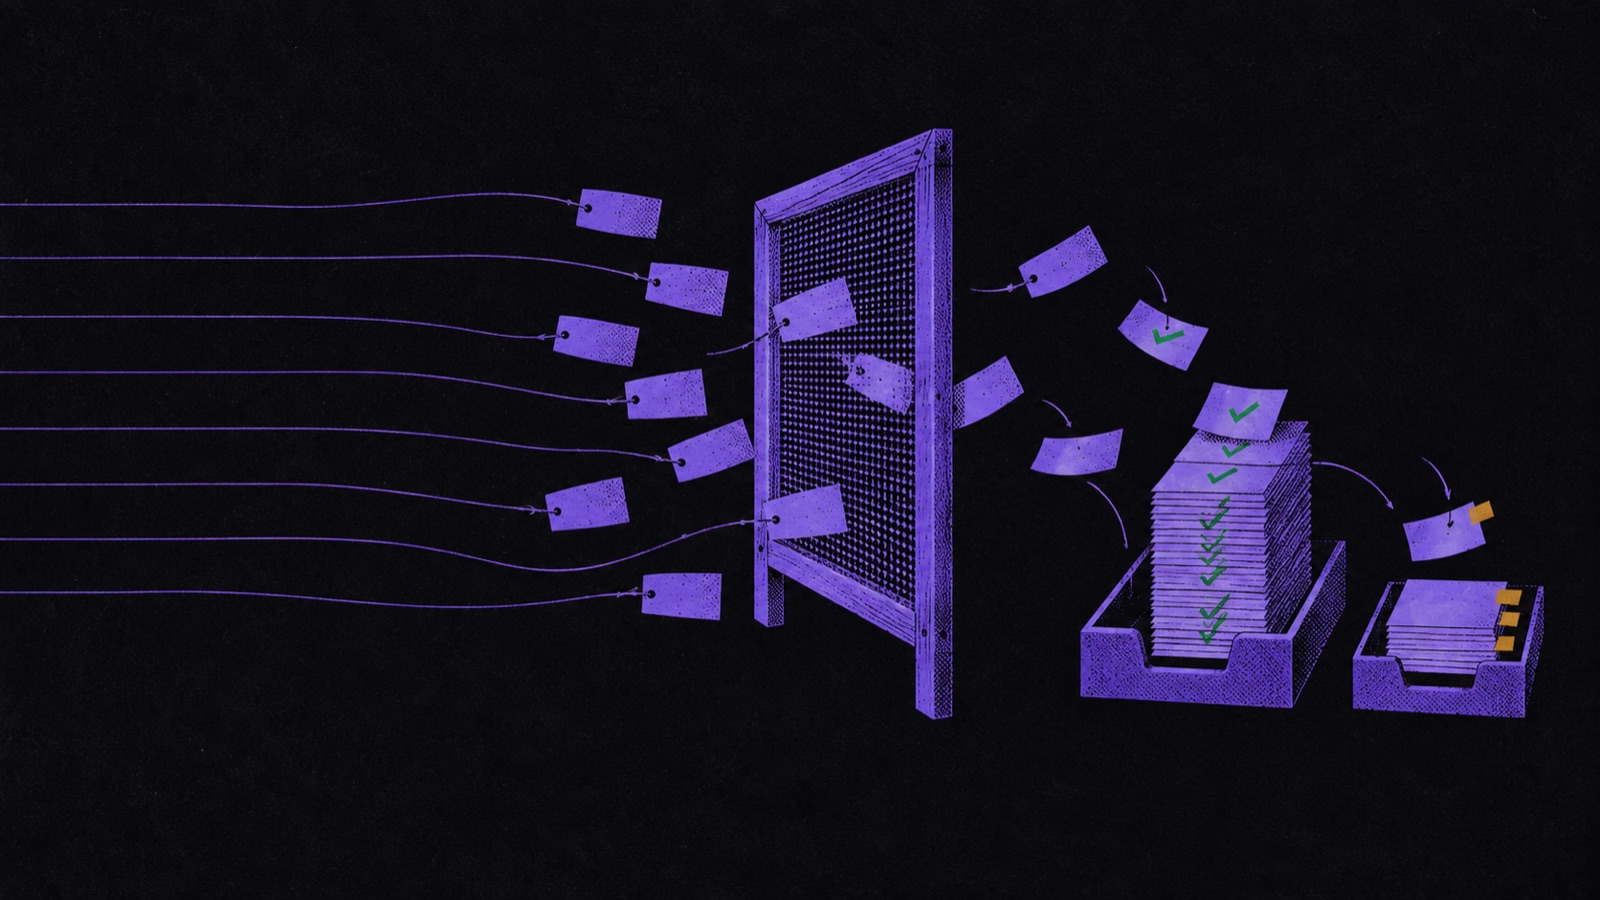
Give it one question and several agents research web and academic sources in parallel, then write it up as a cited report. Every source gets an A–E grade, and any claim not confirmed by two or more sources goes to the appendix instead of the body.
/plugin marketplace add https://github.com/fivetaku/gptaku_plugins.git
/plugin install insane-research@gptaku-plugins
Run `claude plugin marketplace add fivetaku/gptaku_plugins` and `claude plugin install insane-research@gptaku-plugins` in the terminal to install it, then tell me to restart Claude Code.
Real numbers from the sample report below.
From one question to a report
A replay of a real research session (2026-08-23).
Code does the checking
Every claim is logged with its sources, and validate_ledger.py checks that ledger. If it fails, the report isn't written. A model saying "verified" is not enough.
Sample report
Claude Code multi-session app bundle IDs
and Windows notifications
The report we actually used to build our notification plugin, published unedited (in Korean).
Read the original →To be fair
If you just need a quick overview, ChatGPT or Gemini deep research is easier. insane-research asks a few scoping questions and takes longer. Use it for decisions where being wrong is expensive: technology choices, implementation evidence, numbers.
For decisions
you can't afford to get wrong.
/plugin marketplace add https://github.com/fivetaku/gptaku_plugins.git
/plugin install insane-research@gptaku-plugins
Run `claude plugin marketplace add fivetaku/gptaku_plugins` and `claude plugin install insane-research@gptaku-plugins` in the terminal to install it, then tell me to restart Claude Code.